arXiv Research RAG
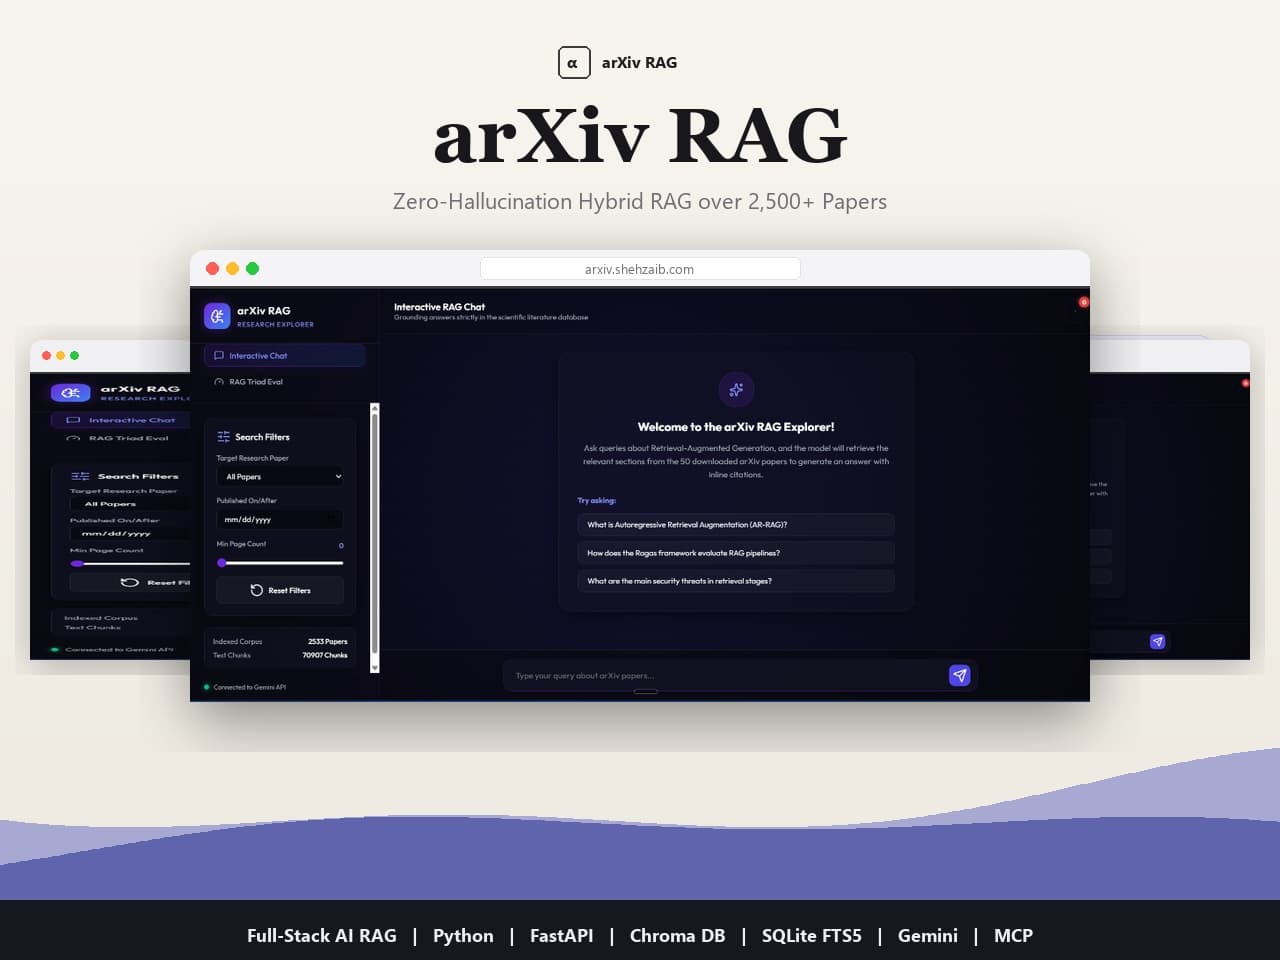
Built a production-grade hybrid RAG system grounded strictly in 2,500+ indexed arXiv research papers. The pipeline blends dense vector search (Chroma DB + Gemini embeddings) with sparse BM25 (SQLite FTS5 inverted index) via Reciprocal Rank Fusion, then cross-encoder reranks with a local Sentence-Transformers ms-marco model. A two-rung refusal ladder aborts LLM generation at $0 cost when confidence falls below a calibrated 70% threshold. When the local corpus lacks coverage, a Model Context Protocol (MCP) client falls back to live arXiv and Semantic Scholar APIs, generates a grounded answer, and auto-ingests new papers into Chroma DB in the background. An embedding-based semantic cache deduplicates paraphrased queries, returning cached answers in milliseconds.
The Problem
Researchers and engineers needed a trustworthy Q&A interface over academic literature that would never hallucinate unsupported claims, even for out-of-corpus queries.
Key Value & Highlights
- ✦Hybrid BM25 + Dense retrieval with RRF blending
- ✦Zero-hallucination refusal ladder at 70% threshold
- ✦Live MCP fallback to arXiv & Semantic Scholar APIs
- ✦Embedding-based semantic cache — $0 cost on cache hits
Technologies Used
Python, FastAPI, Uvicorn, Chroma DB, SQLite FTS5, Gemini Embeddings API, Sentence-Transformers (ms-marco-MiniLM), MCP, arXiv API, Semantic Scholar API, PM2.
Scale & Performance
Indexes 2,500+ papers across 70,000+ text chunks; semantic cache reduces LLM API calls by ~40% on repeated query patterns.
Uptime & Operations
Achieved zero hallucinations on out-of-corpus queries via the refusal ladder. Live MCP fallback expanded effective coverage to all 2M+ arXiv papers on demand, with auto-ingest permanently enriching the local corpus over time.
Ready to build something similar?
Let's discuss how we can build a secure, fast, and scalable SaaS tailored specifically to your roadmap.